Shape

Data Engineering

Categories

Data Engineering

2 article(s) in this category

  • Data Engineering

    Data Engineering Building the Backbone of Data-Driven Systems

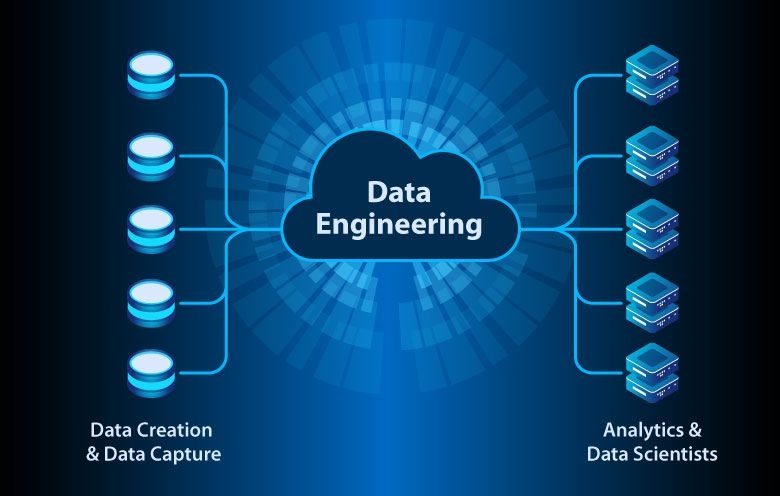
    In a world awash with data—over 2.5 quintillion bytes generated daily—data engineering has emerged as the unsung hero of the digital age. It’s the discipline that transforms raw, chaotic data into structured, reliable systems, enabling everything from real-time analytics to machine learning models. While data scientists uncover insights and developers craft user-facing apps, data engineers lay the foundation, designing pipelines, storage solutions, and processing frameworks that power modern organizations. This article dives into the intricate world of data engineering, exploring its core principles, tools, and practices that fuel data-driven success. The Essence of Data Engineering: Data engineering is the art and science of building robust systems to collect, store, transform, and deliver data at scale. Unlike data science, which focuses on analysis, data engineering is about infrastructure—ensuring data is accessible, accurate, and timely. Picture a sprawling factory: raw materials (data) enter from sources like IoT devices, web apps, or APIs; data engineers design the conveyor belts (pipelines), warehouses (storage), and assembly lines (processing) to turn it into usable products. Companies like Netflix rely on data engineering to stream petabytes of viewing data daily, ensuring seamless recommendations and uptime. It’s a field where reliability trumps experimentation, and scalability is king. Data Pipelines: The Lifelines of Data Flow: At the heart of data engineering lie data pipelines—automated workflows that move data from source to destination, often transforming it along the way. These pipelines handle ETL processes (Extract, Transform, Load): extracting data from a CRM like Salesforce, transforming it by cleaning duplicates or normalizing formats, and loading it into a data warehouse like Snowflake. Tools like Apache Airflow orchestrate these workflows, scheduling tasks and retrying failures, while Apache NiFi offers visual pipeline design. For real-time needs, Apache Kafka streams data instantly—think Twitter processing millions of tweets per minute. A well-built pipeline cuts latency from hours to seconds, but a single bottleneck can grind analytics to a halt, making resilience critical. Storage Solutions: Where Data Lives: Data engineers architect storage systems to handle volume, variety, and velocity. Traditional relational databases (e.g., PostgreSQL) excel for structured data, but big data demands more. Hadoop HDFS distributes petabytes across clusters, tolerating hardware failures with triple replication. Cloud-native options like Amazon S3 offer infinite scalability—storing objects from logs to videos—while Google BigQuery marries storage with query speed for analytics. Data lakes (e.g., Delta Lake) unify raw and processed data, supporting diverse formats like JSON or Parquet. Choosing the right storage means balancing cost (S3 at $0.023/GB/month) with performance (BigQuery’s sub-second queries), ensuring data is both safe and ready when needed. Data Processing: Turning Raw into Refined: Raw data is useless without processing—data engineers wield frameworks to tame it. Apache Spark reigns for batch and streaming, crunching terabytes in memory with its RDDs (Resilient Distributed Datasets); a retailer might use it to aggregate daily sales across 10,000 stores in minutes. For real-time, Apache Flink processes event streams with exactly-once guarantees, powering fraud detection in banks. Batch jobs might run nightly on Hadoop MapReduce, though its disk-based approach lags behind Spark’s speed. Cloud services like AWS Glue automate ETL, while dbt (data build tool) transforms data in-warehouse with SQL. Processing isn’t just speed—it’s about accuracy, as a single misjoin can skew a million-dollar forecast. Data Quality and Governance: Garbage in, garbage out—data engineering demands quality control. Engineers implement validation checks (e.g., schema enforcement, null detection) and monitoring (e.g., Airflow sensors) to catch errors early. Governance ensures compliance with laws like GDPR, anonymizing PII (Personally Identifiable Information) or auditing access via Apache Ranger. Tools like Great Expectations test data integrity—ensuring a sales dataset doesn’t list negative prices—while metadata platforms like Apache Atlas track lineage, showing how data morphed from source to report. Poor quality costs: a 2021 Gartner study pegged bad data at $12.9 million annually for the average firm. Data engineers are the gatekeepers of trust. Conclusion: Data engineering is the bedrock of the data economy, turning a flood of bytes into a stream of value. From crafting pipelines that pulse with real-time data to architecting storage that scales effortlessly, data engineers enable the analytics and AI that define our future. With tools like Spark, Kafka, and S3, they tackle complexity head-on, ensuring data is not just big but usable. As organizations lean harder on data—projected to hit 181 zettabytes by 2025—data engineering’s role will only grow, demanding precision, creativity, and foresight to keep the digital world humming.
    By Sabri MAHMOUDRead Full Article
  • Data Engineering

    The Importance of Data Pipeline Management

    The Importance of Data Pipeline Management In today’s digital era, data has become one of the most valuable assets for businesses of all sizes. However, merely collecting data is not enough to generate value. To effectively transform raw data into actionable insights, organizations need robust and reliable processes to move, transform, and analyze this data. This is where data pipeline management comes in, a foundational element of any modern data-driven strategy. What is a Data Pipeline? A data pipeline is a set of processes and tools that enable the movement of data from various sources to destinations where it can be stored and analyzed. These pipelines automate the flow of data through different processing stages, ensuring that data is collected, cleaned, transformed, and loaded in a consistent and reliable manner. A typical data pipeline includes several essential components: Extraction : Collecting data from various sources (databases, APIs, log files, IoT sensors, etc.) Transformation : Cleaning, enriching, and converting data into a format suitable for analysis Loading : Storing transformed data in a data warehouse, data lake, or another destination Orchestration : Coordinating and scheduling the different stages of the pipeline Monitoring : Tracking the performance and reliability of the pipeline Why is Data Pipeline Management Crucial? 1. Ensuring Data Quality and Reliability Data quality is essential for making informed decisions. Well-managed data pipelines include validation and cleaning mechanisms that identify and correct anomalies, duplicates, and inconsistencies. By establishing quality controls at each stage of the pipeline, organizations can ensure that the data reaching their analytical systems is accurate and reliable. For example, an e-commerce company analyzing purchasing behavior must ensure that transaction data is complete and consistent before using it for product recommendations. A well-designed data pipeline can automatically detect and correct incomplete records or outliers, thereby improving the accuracy of subsequent analyses. 2. Improving Operational Efficiency Automating data flows eliminates error-prone and time-consuming manual processes. Modern data pipelines can be scheduled to run at specific intervals or triggered by particular events, reducing the need for human intervention. This automation allows data teams to focus on higher-value tasks, such as data analysis and interpretation, rather than repetitive data movement and transformation activities. Moreover, well-designed pipelines can scale to handle growing data volumes without requiring proportional additional resources. 3. Enabling Real-Time Decision Making In an increasingly dynamic business environment, the ability to make decisions based on the most current data can provide a significant competitive advantage. Modern data pipelines, particularly those designed for real-time processing, enable organizations to analyze data as it is generated. For instance, a video streaming platform can use real-time data pipelines to analyze user viewing habits and instantly adjust content recommendations. Similarly, a financial institution can detect and prevent fraudulent transactions by analyzing behavioral patterns in real time. 4. Ensuring Data Compliance and Governance With the rise of data protection regulations like the GDPR in Europe or the CCPA in California, organizations must be able to track and document how data is collected, processed, and used. Well-managed data pipelines provide full traceability, enabling companies to demonstrate compliance with regulatory requirements. Pipelines can be configured to automatically enforce data governance policies, such as anonymizing sensitive personal information or implementing role-based access controls. This proactive approach to data governance reduces the risk of compliance breaches and enhances customer trust. 5. Fostering Innovation and Growth Efficient data pipelines enable organizations to fully harness the potential of their data for innovation. By making data accessible and usable, they facilitate the development of new products, services, and business models based on generated insights. For example, an insurance company can analyze driving data to develop personalized insurance policies based on actual driver behavior. A manufacturing firm can use sensor data to optimize production processes and reduce costs. These innovations are made possible by data pipelines that provide reliable and timely access to relevant information. Best Practices for Data Pipeline Management 1. Adopt a Modular Architecture Data pipelines should be designed with a modular architecture that allows individual components to be modified or replaced without disrupting the entire system. This approach simplifies maintenance and evolution of the pipeline over time as business needs and technologies change. 2. Implement Proactive Monitoring Continuous monitoring of data pipelines is essential to quickly identify and resolve potential issues. Automated monitoring tools can alert teams to anomalies such as delays in data processing, high error rates, or performance bottlenecks. 3. Document and Version Pipelines Comprehensive documentation is critical for the maintenance and evolution of data pipelines, especially in large organizations where multiple teams may be involved. Documentation should include details about data sources, applied transformations, validation rules, and dependencies between components. 4. Prioritize Security at Every Stage Data security must be a top consideration in the design and management of data pipelines. This includes encrypting data in transit and at rest, implementing strict access controls, and regularly auditing pipeline activities. 5. Plan for Scalability As the volume, variety, and velocity of data increase, pipelines must be able to adapt without significant performance degradation. This may involve using distributed technologies like Apache Spark or Kafka, which can scale horizontally by adding more nodes to the cluster. Conclusion Effective data pipeline management has become a cornerstone of any successful data-driven strategy. By automating and optimizing data flow across the organization, well-designed pipelines enable businesses to transform raw data into valuable insights, improve operational efficiency, and drive innovation. As the volume and complexity of data continue to grow, the importance of robust data pipeline management will only increase. Organizations that invest in developing reliable, scalable, and secure pipelines will be better positioned to fully leverage their data’s potential and maintain a competitive edge in the digital economy.

    By Sabri MAHMOUDRead Full Article
Shape